
Mapping Data Between AI Agent Steps
This post explains how to map data between steps in AI agent workflows, covering three core patterns: direct pass-through, field extraction, and transformation. It emphasizes structured output from LLMs as the key to reliable workflow integration and offers practical Python-based examples for IT pr

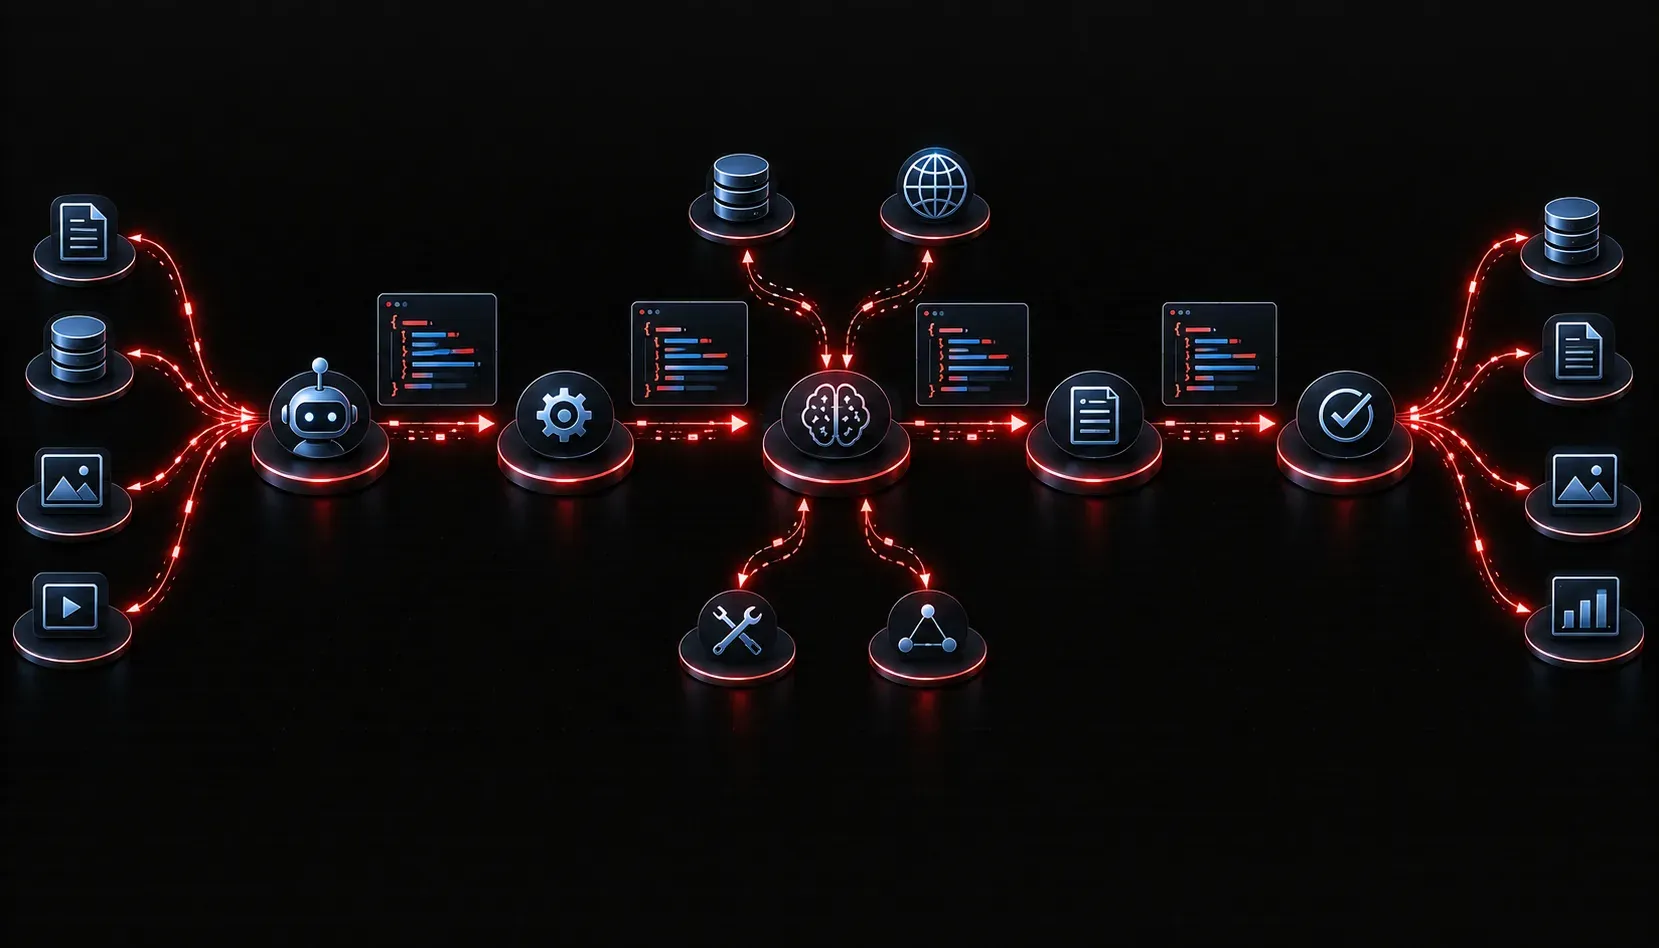
When you build an AI agent that performs multiple steps, one of the most common headaches is getting the output of one step to cleanly feed into the next. This is called mapping data between agent steps, and if you skip planning it properly, your workflow falls apart fast.
Think of it like a relay race. Each runner (agent step) needs to receive the baton (data) in exactly the right way, at exactly the right moment. Drop the baton and the race is over. In agentic AI workflows, the baton is structured data moving between tools, prompts, and APIs.
Why Data Mapping Matters in Agentic AI
Modern AI agents do not just run a single prompt. They chain together multiple steps: pulling information from an API, summarizing it with a language model, storing results in a database, then triggering a downstream action. Each of those steps expects data in a specific format. Without intentional AI data mapping, you end up with type mismatches, missing fields, and broken pipelines.
The problem gets worse when you mix different tools. A web search tool might return raw text. Your LLM prompt might expect a JSON object. A ticketing system API might require a specific schema with required fields. Bridging those gaps is the job of data mapping.
The Three Common Mapping Patterns
1. Direct Pass-Through
The simplest case: the output of one step is used as-is in the next. This works when both steps agree on format. For example, if your agent fetches a plain text article and immediately sends it to a summarization prompt, no transformation is needed.
{
  "step_1_output": "Article text goes here...",
  "step_2_input": "Article text goes here..."
}
This is rare in real workflows, but it is worth recognizing when you have it because it simplifies your design significantly.
2. Field Extraction
More commonly, you need to pull specific fields from a larger output and pass only what is needed. If your LLM returns a structured JSON object, you might extract just one field before passing it forward.
# Step 1 output (LLM structured response)
{
  "customer_name": "Alice Johnson",
  "issue_summary": "Unable to connect to VPN",
  "severity": "high",
  "suggested_action": "Restart IKE service"
}

# Step 2 only needs the ticket fields
{
  "title": "Unable to connect to VPN",
  "priority": "high"
}
In Python-based frameworks like LangChain or LlamaIndex, you handle this with output parsers or by referencing specific keys from the previous step's result dictionary.
3. Transformation and Enrichment
Sometimes you need to transform the data entirely, combining, renaming, or reformatting fields to match a downstream schema. This is the most involved pattern and requires explicit mapping logic.
# Incoming data from agent step
raw = {
  "full_name": "Alice Johnson",
  "issue": "VPN failure",
  "level": 2
}

# Mapped output for ticketing API
mapped = {
  "requester": raw["full_name"],
  "subject": raw["issue"],
  "priority": "high" if raw["level"] >= 2 else "normal"
}
This kind of logic lives in what is called a transformation node or data mapper in workflow tools like n8n, Make (formerly Integromat), or custom Python code in your agent orchestrator.
Structured Output: Your Best Friend
The single most effective thing you can do to simplify mapping data in AI agents is to enforce structured output from your LLM steps. Instead of asking the model to return free text, instruct it to return a specific JSON schema. OpenAI's API supports this natively with the response_format parameter set to json_object or a defined JSON schema.
When your LLM reliably returns the same field names in the same types every time, downstream mapping becomes predictable and testable. Unpredictable free-text responses are the root cause of most workflow integration failures in agentic pipelines.
Practical Tips for Cleaner Data Mapping
- Define your schema early: Before writing any prompts, sketch out what data each step needs to receive and produce.
- Use type validation: In Python, libraries like
pydanticlet you validate and coerce data between steps automatically. - Log intermediate outputs: During development, print or log the output of every step so you can see exactly what is flowing through your pipeline.
- Name fields consistently: Agree on naming conventions across all steps. Mixing
customer_name,customerName, andnamefor the same concept is a fast path to bugs.
What's Next
Now that you understand how data flows between agent steps, the next natural topic is handling errors and fallbacks in agentic workflows. What happens when a step returns unexpected data, an API times out, or the LLM produces output that fails validation? Knowing how to build resilient pipelines is what separates a demo from a production-ready agent.