
How to Use Ping and Traceroute for Network Issues
This post walks through how to use ping and traceroute to diagnose network connectivity problems step by step. It covers reading command output, identifying failure points at specific hops, and following a logical troubleshooting workflow. Practical CLI examples are included for both Windows and Li
When something stops working on a network, the first question is almost always: "Can this device reach that device?" Before you start pulling cables or rebooting switches, two simple tools can tell you a remarkable amount about what is actually happening: ping and traceroute. These utilities are available on virtually every operating system and are your first line of defense when diagnosing network issues.
What Does Ping Actually Do?
ping sends ICMP Echo Request packets to a target host and waits for ICMP Echo Reply packets in return. Think of it like shouting across a room and listening for an answer. If you get a reply, basic connectivity exists. If you do not, something is blocking the path.
Here is what a successful ping looks like on a Windows machine:
C:\> ping 8.8.8.8

Pinging 8.8.8.8 with 32 bytes of data:
Reply from 8.8.8.8: bytes=32 time=14ms TTL=117
Reply from 8.8.8.8: bytes=32 time=13ms TTL=117
Reply from 8.8.8.8: bytes=32 time=14ms TTL=117
Reply from 8.8.8.8: bytes=32 time=14ms TTL=117

Ping statistics for 8.8.8.8:
    Packets: Sent = 4, Received = 4, Lost = 0 (0% loss),
Approximate round trip times in min/max/avg = 13/14/14 ms
Pay attention to three things in this output:
- Packet loss: Any percentage above zero warrants investigation.
- Round-trip time (RTT): High or inconsistent values can indicate congestion or a degraded link.
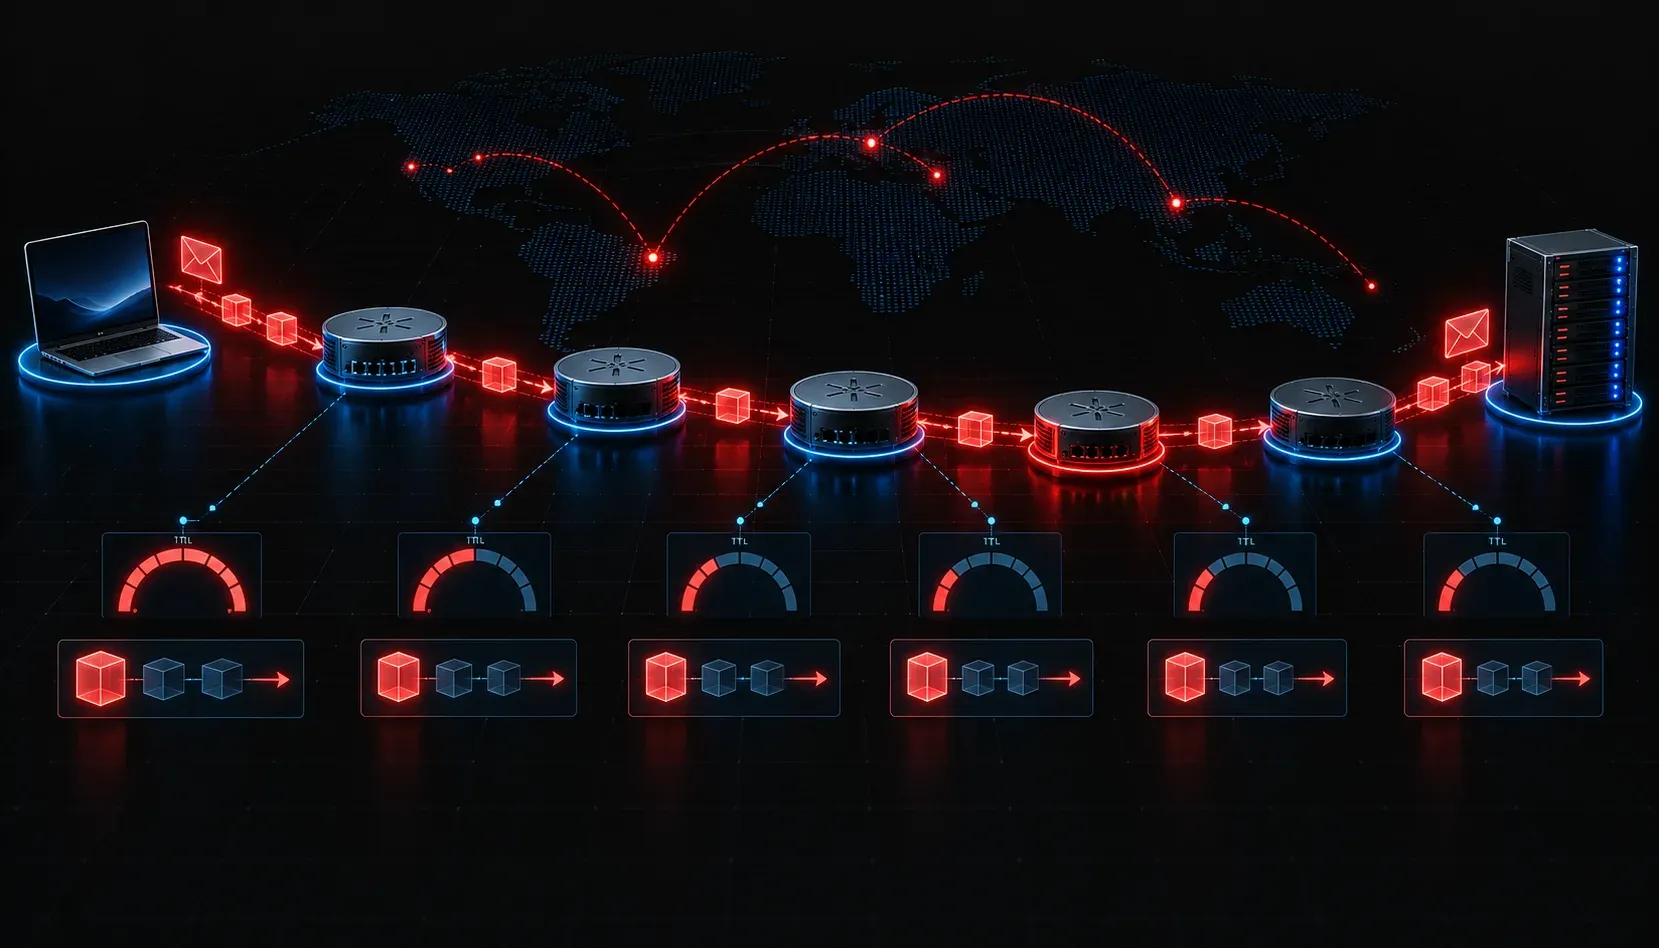
- TTL value: The Time to Live field decrements at each hop. A very low TTL value on the reply can suggest the destination is many hops away.
On Linux and macOS, ping runs continuously until you stop it with Ctrl+C. On Windows, it sends four packets by default. Use ping -t on Windows for continuous pinging.
Using Traceroute to Follow the Path
When ping fails or shows problems, traceroute (called tracert on Windows) helps you identify exactly where the breakdown occurs. It works by sending packets with incrementally increasing TTL values, causing each router along the path to respond with an ICMP Time Exceeded message. The result is a hop-by-hop map of the route your traffic takes.
C:\> tracert 8.8.8.8

Tracing route to dns.google [8.8.8.8]
over a maximum of 30 hops:

  1     2 ms     1 ms     1 ms  192.168.1.1
  2    12 ms    11 ms    12 ms  10.0.0.1
  3    13 ms    13 ms    12 ms  72.14.202.1
  4    14 ms    13 ms    14 ms  8.8.8.8

Trace complete.
Reading the Output
Each row represents one router hop. The three time values are three separate probes to that hop. Here is what to look for when diagnosing issues:
- Asterisks (* * *): The hop did not respond. This could mean the router is blocking ICMP, or there is a genuine failure at that point.
- Latency spike at a specific hop: If times jump significantly at one particular hop and stay high beyond it, that hop is likely the bottleneck.
- Trace stops mid-path: If the output stops before reaching the destination, the last responding hop is where traffic is being dropped or filtered.
A Practical Troubleshooting Workflow
Use these tools together in a logical sequence to diagnose issues efficiently:
- Ping the loopback address (
127.0.0.1) to confirm the local network stack is functional. - Ping your default gateway to confirm local connectivity.
- Ping a known external address like
8.8.8.8to test internet reachability. - Ping a domain name like
google.comto confirm DNS resolution is working. - If any step fails, run
tracerouteto identify the point of failure.
This layered approach helps you narrow down whether you have a local device issue, a gateway problem, an ISP issue, or a DNS failure, without guessing.
Important Caveats
Not every failed ping means the host is down. Some firewalls and devices are configured to silently drop ICMP packets. A host may be fully reachable on port 80 or 443 while not responding to ping at all. Always consider firewall rules before concluding a device is offline.
What's Next
Now that you know how to test connectivity and trace a path, the next step is understanding how to read and interpret IP addressing at each hop. Our upcoming post on subnetting fundamentals will give you the context you need to understand why traffic takes specific routes and where address misconfigurations hide.
Tools and resources for this topic
- CompTIA Network+ Study Guide — Comprehensive N10-009 exam preparation covering all five domains.