
Comparing Debugging and Monitoring Tools for Effective Network Assurance
This post compares the major categories of network troubleshooting tools available to CCNP-level engineers, including debug commands, SNMP, IP SLA, NetFlow, model-driven telemetry, and SPAN variants. It covers real-world tradeoffs, configuration examples, and a scenario-based selection matrix to he
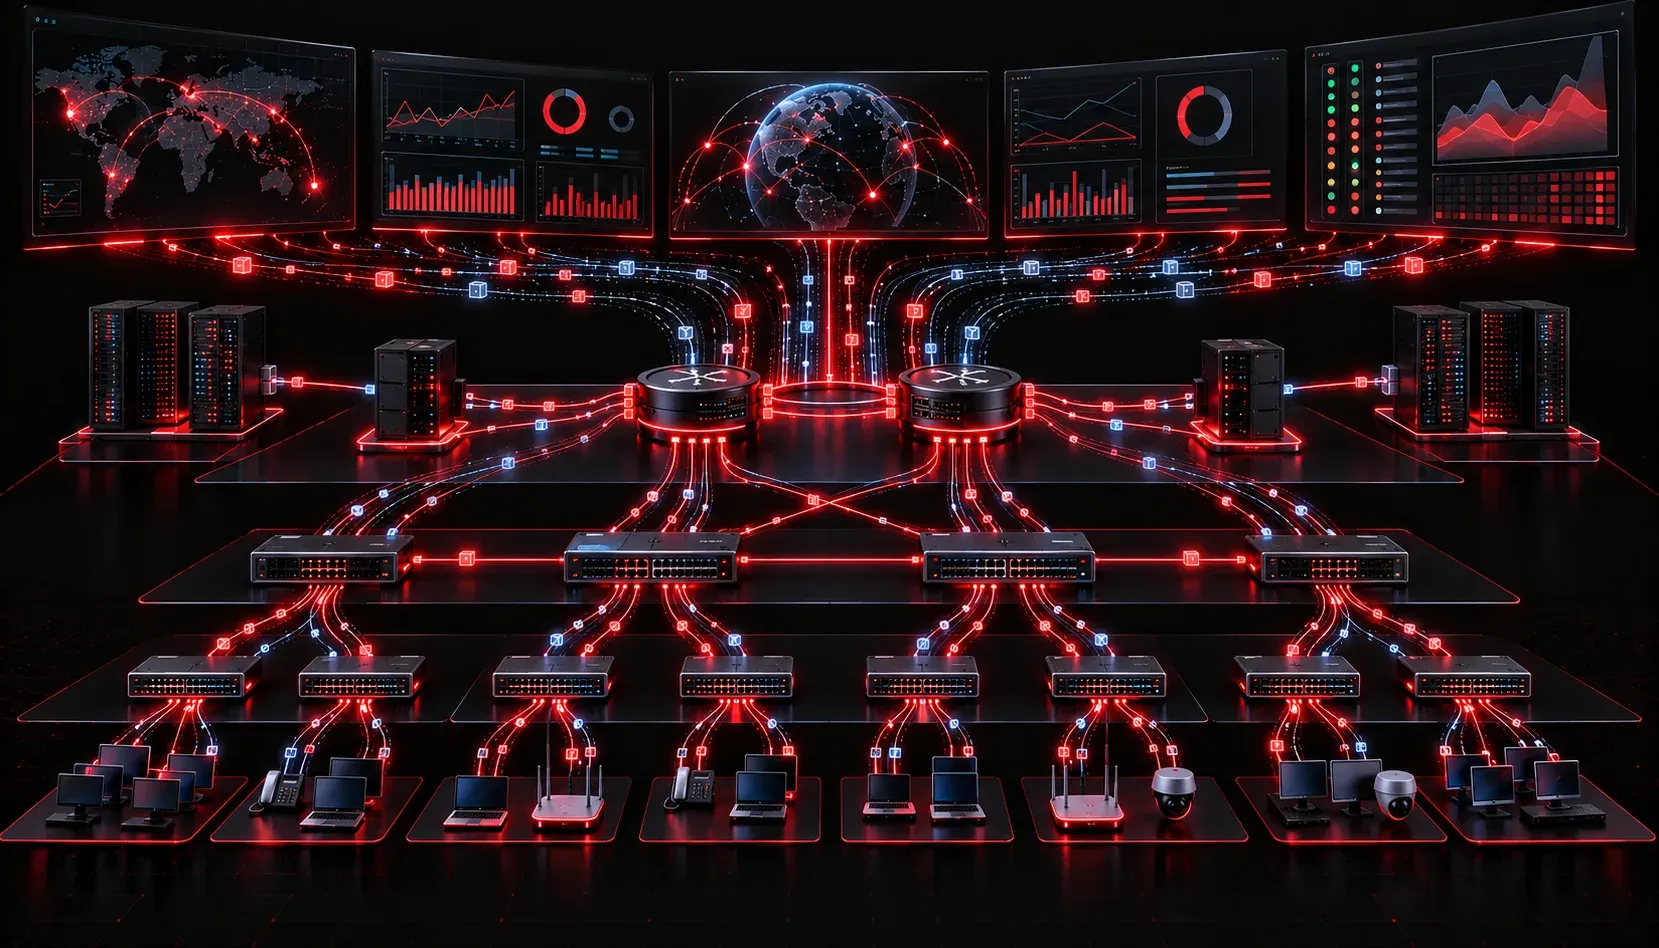
Choosing the wrong tool for a troubleshooting scenario doesn't just slow you down; it can actively mislead you. A debug command that floods the control plane during a production incident, or a monitoring platform that only polls every five minutes when you need millisecond granularity, both represent the same failure: using the right tool in the wrong context. This post breaks down the major categories of network troubleshooting tools, their real-world tradeoffs, and how to select the right one for the job, both on the ENCOR exam and in production.
Tool Categories and Their Purpose
Network assurance tools fall into a few broad categories, each designed for a different phase of the troubleshooting lifecycle:
- Real-time debugging tools:
debug,conditional debug, Embedded Event Manager (EEM) - Passive monitoring tools: SNMP, NetFlow/IPFIX, syslog, SPAN/RSPAN/ERSPAN
- Active probing tools: IP SLA, Cisco DNA Center Assurance, ping, traceroute
- Flow and telemetry tools: Model-driven telemetry (MDT), gRPC streaming, YANG data models
Understanding where each category excels, and where it fails, is the core of the ENCOR 4.1 objective around tool evaluation.
Debug vs. Monitoring: The Fundamental Tradeoff
The debug command family gives you real-time, per-packet visibility at the cost of CPU overhead. On a busy router or switch, enabling broad debugs can spike CPU to the point of impacting forwarding. This is not theoretical; process-switched debug output competes directly with routing protocol processing and management plane functions.
Use conditional debugging to scope the blast radius. For example, to debug only traffic from a specific IP:
debug condition interface GigabitEthernet0/1
debug ip packet detail
Or scope by IP address using access lists:
ip access-list extended DEBUG_FILTER
 permit ip host 10.1.1.1 any

debug ip packet detail 101
This reduces the volume of output without sacrificing specificity. Always remember to disable debugs once the capture is complete with undebug all. Leaving debugs running in production is a reliability risk, not just a performance concern.
SNMP polling, by contrast, has zero impact on forwarding but introduces a fundamental limitation: polling interval latency. A five-minute poll cycle means you can miss transient events entirely. SNMP traps address this partially, but trap delivery itself is unreliable over UDP and depends on the management station being reachable when the event occurs.
IP SLA: Active Probing Done Right
IP SLA is one of the most underutilized tools in the enterprise toolkit. It generates synthetic test traffic to measure real performance metrics: latency, jitter, packet loss, and MOS scores for voice paths. Unlike passive tools that depend on actual user traffic, IP SLA works even when the application is idle.
A basic UDP jitter probe targeting a remote responder looks like this:
ip sla 10
 udp-jitter 10.2.2.2 5000 num-packets 20 interval 20
 frequency 60
ip sla schedule 10 life forever start-time now

ip sla responder
 udp-echo ipaddress 10.2.2.2 port 5000
Verify results with:
show ip sla statistics 10
The output gives you round-trip time, jitter averages, and packet loss counts. For voice and video paths, this is far more meaningful than a simple ping. IP SLA also integrates directly with object tracking for reliable failover triggers, making it dual-purpose as both a monitoring and a control-plane automation tool.
NetFlow and IPFIX: Traffic Pattern Analysis
When you need to understand traffic composition rather than per-packet behavior, NetFlow and its standardized successor IPFIX are the right tools. These export flow records to a collector and give you visibility into source/destination pairs, protocol distribution, top talkers, and traffic volume trends.
The key tradeoff with NetFlow is sampling. On high-speed interfaces, sampled NetFlow (typically 1:1000 or 1:512) reduces export overhead but means you're working with statistical approximations, not exact counts. For security investigations, this matters. For capacity planning, it's generally acceptable.
flow record ENCOR_RECORD
 match ipv4 source address
 match ipv4 destination address
 match transport source-port
 match transport destination-port
 match ip protocol
 collect counter bytes
 collect counter packets

flow exporter ENCOR_EXPORTER
 destination 10.100.1.50
 transport udp 9996

flow monitor ENCOR_MONITOR
 record ENCOR_RECORD
 exporter ENCOR_EXPORTER
 cache timeout active 60

interface GigabitEthernet0/0
 ip flow monitor ENCOR_MONITOR input
Model-Driven Telemetry: The Modern Standard
Traditional SNMP pull-based polling is giving way to model-driven telemetry (MDT) with gRPC transport. MDT pushes data from the device to a collector on a configurable cadence, often at sub-second intervals. This eliminates the polling latency problem and scales better for large deployments.
On IOS XE, a basic MDT subscription looks like this:
telemetry ietf subscription 101
 encoding encode-kvgpb
 filter xpath /interfaces/interface/statistics
 stream yang-push
 update-policy periodic 1000
 receiver ip address 10.100.1.60 57000 protocol grpc-tcp
The update-policy periodic 1000 value is in centiseconds, so this pushes interface statistics every 10 seconds. Pair this with a stack like Telegraf, InfluxDB, and Grafana (the TIG stack) and you have production-grade dashboarding with near-real-time data.
SPAN, RSPAN, and ERSPAN: Packet Capture at Scale
When you need full packet captures for protocol analysis or security forensics, SPAN variants give you a copy of the traffic at wire rate. Local SPAN is the simplest but requires physical access to the switch. RSPAN extends the capture across a VLAN to a remote switch. ERSPAN encapsulates the mirrored traffic in GRE and sends it to an IP destination, making it suitable for captures across routed domains or to cloud-based analysis tools.
ERSPAN is the right choice when your packet capture workstation is not directly connected to the segment under analysis. Combine it with Wireshark and you have a powerful capture pipeline that works across any topology.
Tool Selection Matrix
- Transient control-plane events (BGP flap, OSPF adjacency drop):
debugwith conditional filters, syslog with buffered logging - Sustained performance degradation (latency, jitter, loss): IP SLA with UDP jitter probes
- Traffic composition and top-talker analysis: NetFlow/IPFIX with a collector
- Real-time dashboard and anomaly detection: Model-driven telemetry with gRPC
- Protocol-level forensics and security analysis: ERSPAN to a Wireshark capture point
- Long-term trending and capacity planning: SNMP with an NMS platform (SolarWinds, LibreNMS, PRTG)
What's Next
With a solid understanding of how to select the right tool for each troubleshooting scenario, the next step is diving into how Cisco DNA Center Assurance abstracts and automates many of these data sources into a unified network assurance platform. We'll cover how DNA Center correlates telemetry, client health scoring, and AI-driven root cause analysis, and how those concepts map directly to the ENCOR 4.x domain.
Tools and resources for this topic
- CCNP ENCOR 350-401 Official Cert Guide — The definitive ENCOR study resource by Brad Edgeworth. Covers enterprise infrastructure, virtualisation, and automation.