
Deploying AI-Powered Applications: Strategies and Tools
This post walks beginners through deploying AI-powered applications into production, covering environment configuration, wrapping AI logic in a FastAPI layer, choosing a deployment platform, and monitoring costs and performance. It provides working code examples and practical tool recommendations f
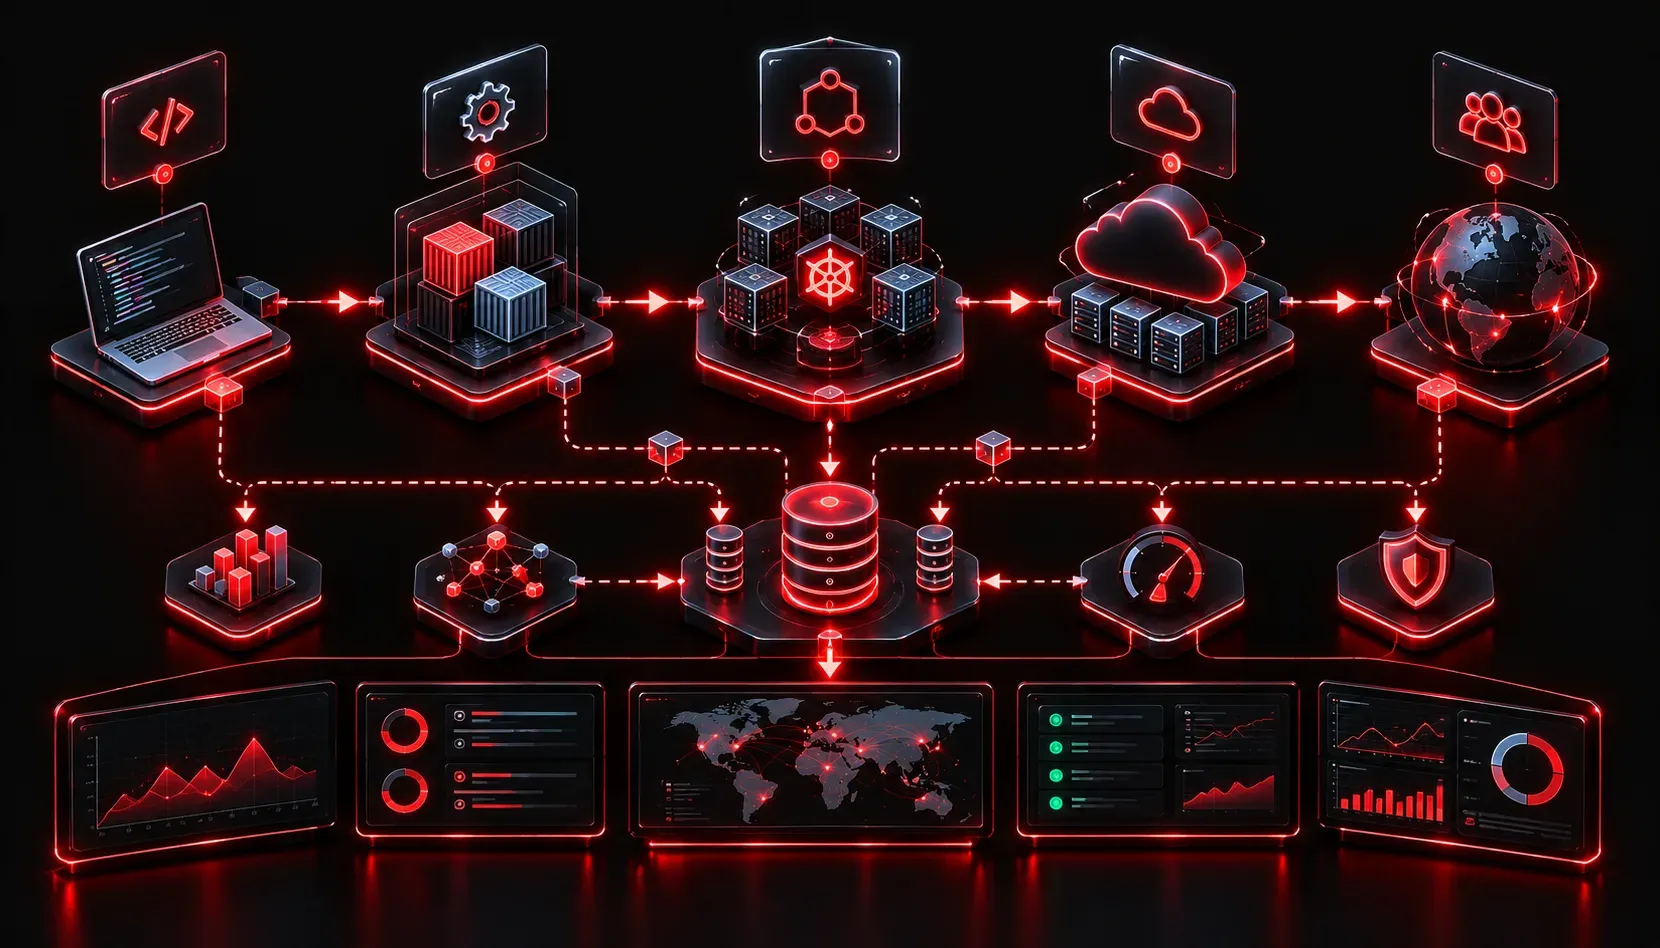
You have trained your model, written your prompts, and tested your application locally. Now comes the part that many beginners underestimate: actually deploying AI applications into a production environment where real users interact with them. This step requires more planning than a traditional software deployment because AI components bring unique challenges around latency, cost, reliability, and model versioning.
This post walks through practical strategies and tools for getting your AI-powered application from your laptop into production without things catching fire on launch day.
Why AI Deployment Is Different
Traditional applications are relatively predictable. AI-powered applications introduce variables that change over time. Models get updated by providers, prompt outputs vary with temperature settings, API rate limits get hit under load, and token costs can spike unexpectedly. A solid AI deployment strategy accounts for all of these upfront.
There are also two distinct deployment patterns worth understanding early:
- API-based deployment: Your application calls an external model provider (like OpenAI or Anthropic) at runtime. You manage your app; they manage the model.
- Self-hosted deployment: You run the model yourself using tools like Ollama or vLLM. More control, more infrastructure responsibility.
For most beginners building on top of existing LLMs, API-based deployment is the right starting point.
Stage 1: Environment and Configuration Management
Before your first production deploy, separate your configuration from your code. API keys, model names, and endpoint URLs should live in environment variables, not hardcoded in your scripts.
A basic .env file might look like this:
OPENAI_API_KEY=sk-xxxxxxxxxxxxxxxxxxxxxxxx
MODEL_NAME=gpt-4o
MAX_TOKENS=1024
TEMPERATURE=0.3
Load these in Python using the python-dotenv library or, in production, inject them through your cloud platform's secret management service. AWS Secrets Manager, Azure Key Vault, and Google Cloud Secret Manager all handle this well.
Stage 2: Wrapping Your AI Logic in an API
Your AI logic should be exposed through a clean API layer. This decouples the model interaction from your frontend and makes the system easier to scale, test, and swap components in later. FastAPI is a popular choice for Python-based AI backends because it is fast, handles async requests well, and auto-generates documentation.
A minimal FastAPI endpoint for an AI feature looks like this:
from fastapi import FastAPI
from openai import OpenAI
import os

app = FastAPI()
client = OpenAI(api_key=os.getenv("OPENAI_API_KEY"))

@app.post("/summarize")
async def summarize(text: str):
    response = client.chat.completions.create(
        model=os.getenv("MODEL_NAME", "gpt-4o"),
        messages=[
            {"role": "system", "content": "Summarize the following text concisely."},
            {"role": "user", "content": text}
        ]
    )
    return {"summary": response.choices[0].message.content}
Run it locally with uvicorn main:app --reload before deploying anywhere.
Stage 3: Choosing a Deployment Platform
For API-based AI applications, several platforms make production integration straightforward:
- Railway or Render: Simple container-based deployments ideal for small projects and prototypes. Connect your GitHub repo and deploy in minutes.
- AWS Lambda or Google Cloud Run: Serverless options that scale to zero when idle, which helps control costs when usage is unpredictable.
- Docker plus a VPS: Full control option. Containerize your app with a
Dockerfile, push to a server, and usenginxas a reverse proxy.
Containerizing your app with Docker ensures consistent behavior across development and production environments. A basic Dockerfile for your FastAPI app:
FROM python:3.11-slim
WORKDIR /app
COPY requirements.txt .
RUN pip install -r requirements.txt
COPY . .
CMD ["uvicorn", "main:app", "--host", "0.0.0.0", "--port", "8000"]
Stage 4: Monitoring and Cost Controls
AI deployment does not end at launch. You need visibility into what your application is doing in production. Key things to monitor include:
- Token usage: Track tokens per request to spot runaway prompts early.
- Latency: AI API calls can be slow. Log response times and set client-side timeouts.
- Error rates: Rate limit errors and API timeouts need alerting, not silent failures.
Tools like LangSmith (from LangChain) and Langfuse provide observability dashboards built specifically for LLM applications. Both offer free tiers that are more than sufficient for getting started.
What's Next
With your AI application running in production, the next area to explore is testing AI behavior systematically. Unlike traditional unit tests, AI outputs are probabilistic, which means you need evaluation frameworks that can measure quality at scale. The next post in this series covers exactly that: how to build eval pipelines that give you confidence your AI features are working as intended before and after every deployment.