
XPATH Basics: Navigating XML Documents
XPath is a powerful language for navigating and querying XML documents using path-like expressions. This post covers the core syntax including absolute and relative paths, predicates, attributes, and common XPath functions, with practical Python examples using the lxml library.
What is XPath and Why Should You Care?
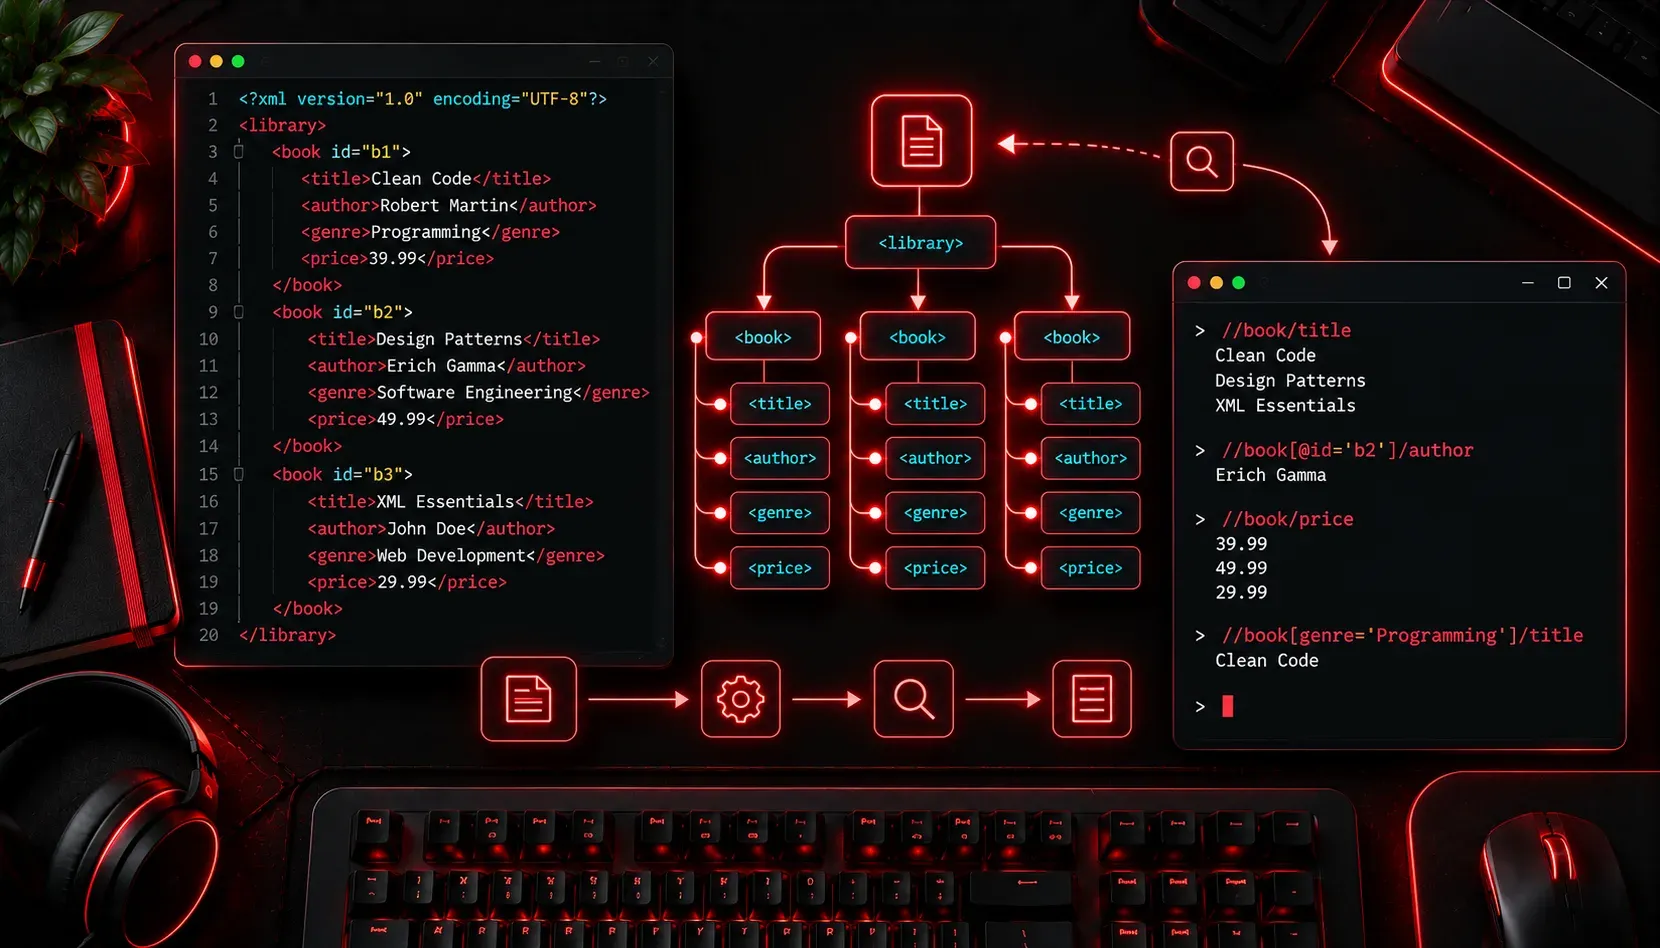
If you have ever worked with XML data, you know how quickly it can become a maze of nested tags and attributes. XPath (XML Path Language) is the tool that lets you navigate that maze with precision. Think of it like a file system path, but instead of pointing to a folder on your hard drive, it points to a specific node inside an XML document.
XPath is used everywhere: web scraping with Python, XSLT transformations, network automation with NETCONF, and even testing frameworks. Learning the basics will unlock a lot of doors across different technical domains.
Understanding the XML Tree Structure
Before writing XPath expressions, you need to understand how XML is structured. Every XML document is a tree of nodes. There is one root element, and everything else branches from it. Consider this simple example:
<network>
  <device>
    <name>Router-1</name>
    <type>router</type>
    <ip>192.168.1.1</ip>
  </device>
  <device>
    <name>Switch-1</name>
    <type>switch</type>
    <ip>192.168.1.2</ip>
  </device>
</network>
Here, network is the root element. Each device is a child node, and name, type, and ip are children of each device. XPath expressions describe a path through this tree to find exactly what you need.
Writing Your First XPath Expressions
Absolute vs. Relative Paths
An absolute path starts from the root of the document, using a leading forward slash:
/network/device/nameA relative path starts from the current context node and uses a double slash to search anywhere in the document:
//nameThe double slash is powerful because it finds all matching nodes regardless of where they sit in the tree. Use it carefully though: on large documents, it can be slow because it searches everywhere.
Selecting Specific Nodes with Predicates
Predicates are filters written inside square brackets. They let you narrow down your selection based on conditions:
/network/device[type='router']/nameThis expression selects the name of any device whose type equals router. You can also select by position:
/network/device[1]/nameNote that XPath uses 1-based indexing, not 0-based. The first device is at position [1], not [0].
Working with Attributes
Attributes in XML are selected using the @ symbol. Imagine your XML used attributes instead of child elements:
<device name="Router-1" type="router" ip="192.168.1.1"/>To select the name attribute, you would write:
/network/device/@nameTo filter by an attribute value:
/network/device[@type='router']/@ipUsing XPath in Python
Python's lxml library makes it straightforward to run XPath queries against real XML documents. Here is a working example using the XML structure from above:
from lxml import etree

xml_data = """
<network>
  <device>
    <name>Router-1</name>
    <type>router</type>
    <ip>192.168.1.1</ip>
  </device>
  <device>
    <name>Switch-1</name>
    <type>switch</type>
    <ip>192.168.1.2</ip>
  </device>
</network>
"""

root = etree.fromstring(xml_data)

# Select all device names
names = root.xpath("/network/device/name/text()")
print(names)
# Output: ['Router-1', 'Switch-1']

# Select only the router's IP
router_ip = root.xpath("/network/device[type='router']/ip/text()")
print(router_ip)
# Output: ['192.168.1.1']
Notice the use of /text() at the end of each expression. This is an XPath function that extracts the text content of a node rather than returning the node object itself.
Helpful XPath Functions to Know
- text(): Selects the text content of a node
- contains(): Checks if a string contains a substring, e.g.
//device[contains(name, 'Router')] - count(): Returns the number of matching nodes, e.g.
count(//device) - last(): Selects the last node in a set, e.g.
/network/device[last()] - not(): Negates a condition, e.g.
//device[not(type='router')]
What's Next
Now that you have a solid grasp of XPath basics, the natural next step is exploring XSLT (Extensible Stylesheet Language Transformations), which uses XPath expressions to transform XML documents into different formats, including HTML, plain text, or even another XML structure. You can also dive deeper into how XPath powers NETCONF-based network automation, where configuration data is structured as XML and queried using these same techniques.
For further practice, check out the official W3Schools XPath Tutorial and experiment interactively at FreeFormatter's XPath Tester, where you can paste in your own XML and test expressions live.